NeurIPS 2026 · Sydney
December 11, 2026
Interpretability as a Science
Toward rigorous foundations for understanding LLMs
About
As large language models grow in capability, interpretability asks how and why they behave as they do. Yet the field has not converged on notions of explanations at varying levels of abstraction, what evidence supports a claim, or how to design experiments that rule out alternative explanations. This workshop asks what it would take to ground interpretability as a rigorous empirical science—drawing lessons from disciplines that have long studied complex systems.
We focus on the following questions:
- What does it mean to understand an LLM?
- What standards, benchmarks, or evaluation criteria the field could adopt for measurement, causal claims, and falsifiability?
- What can interpretability learn from neuroscience, statistics, and causal representation learning?
A distinctive feature of this workshop is its interactive format. The workshop will host multiple breakout sessions, each led by a facilitator from a relevant discipline, who will give a short lightning talk highlighting important questions related to a specific sub-theme, then moderate a discussion connecting these ideas to interpretability. This format is designed to encourage genuine dialogue and engagement, inviting attendees to collectively shape a shared scientific foundation for interpretability.
Invited Speakers
-
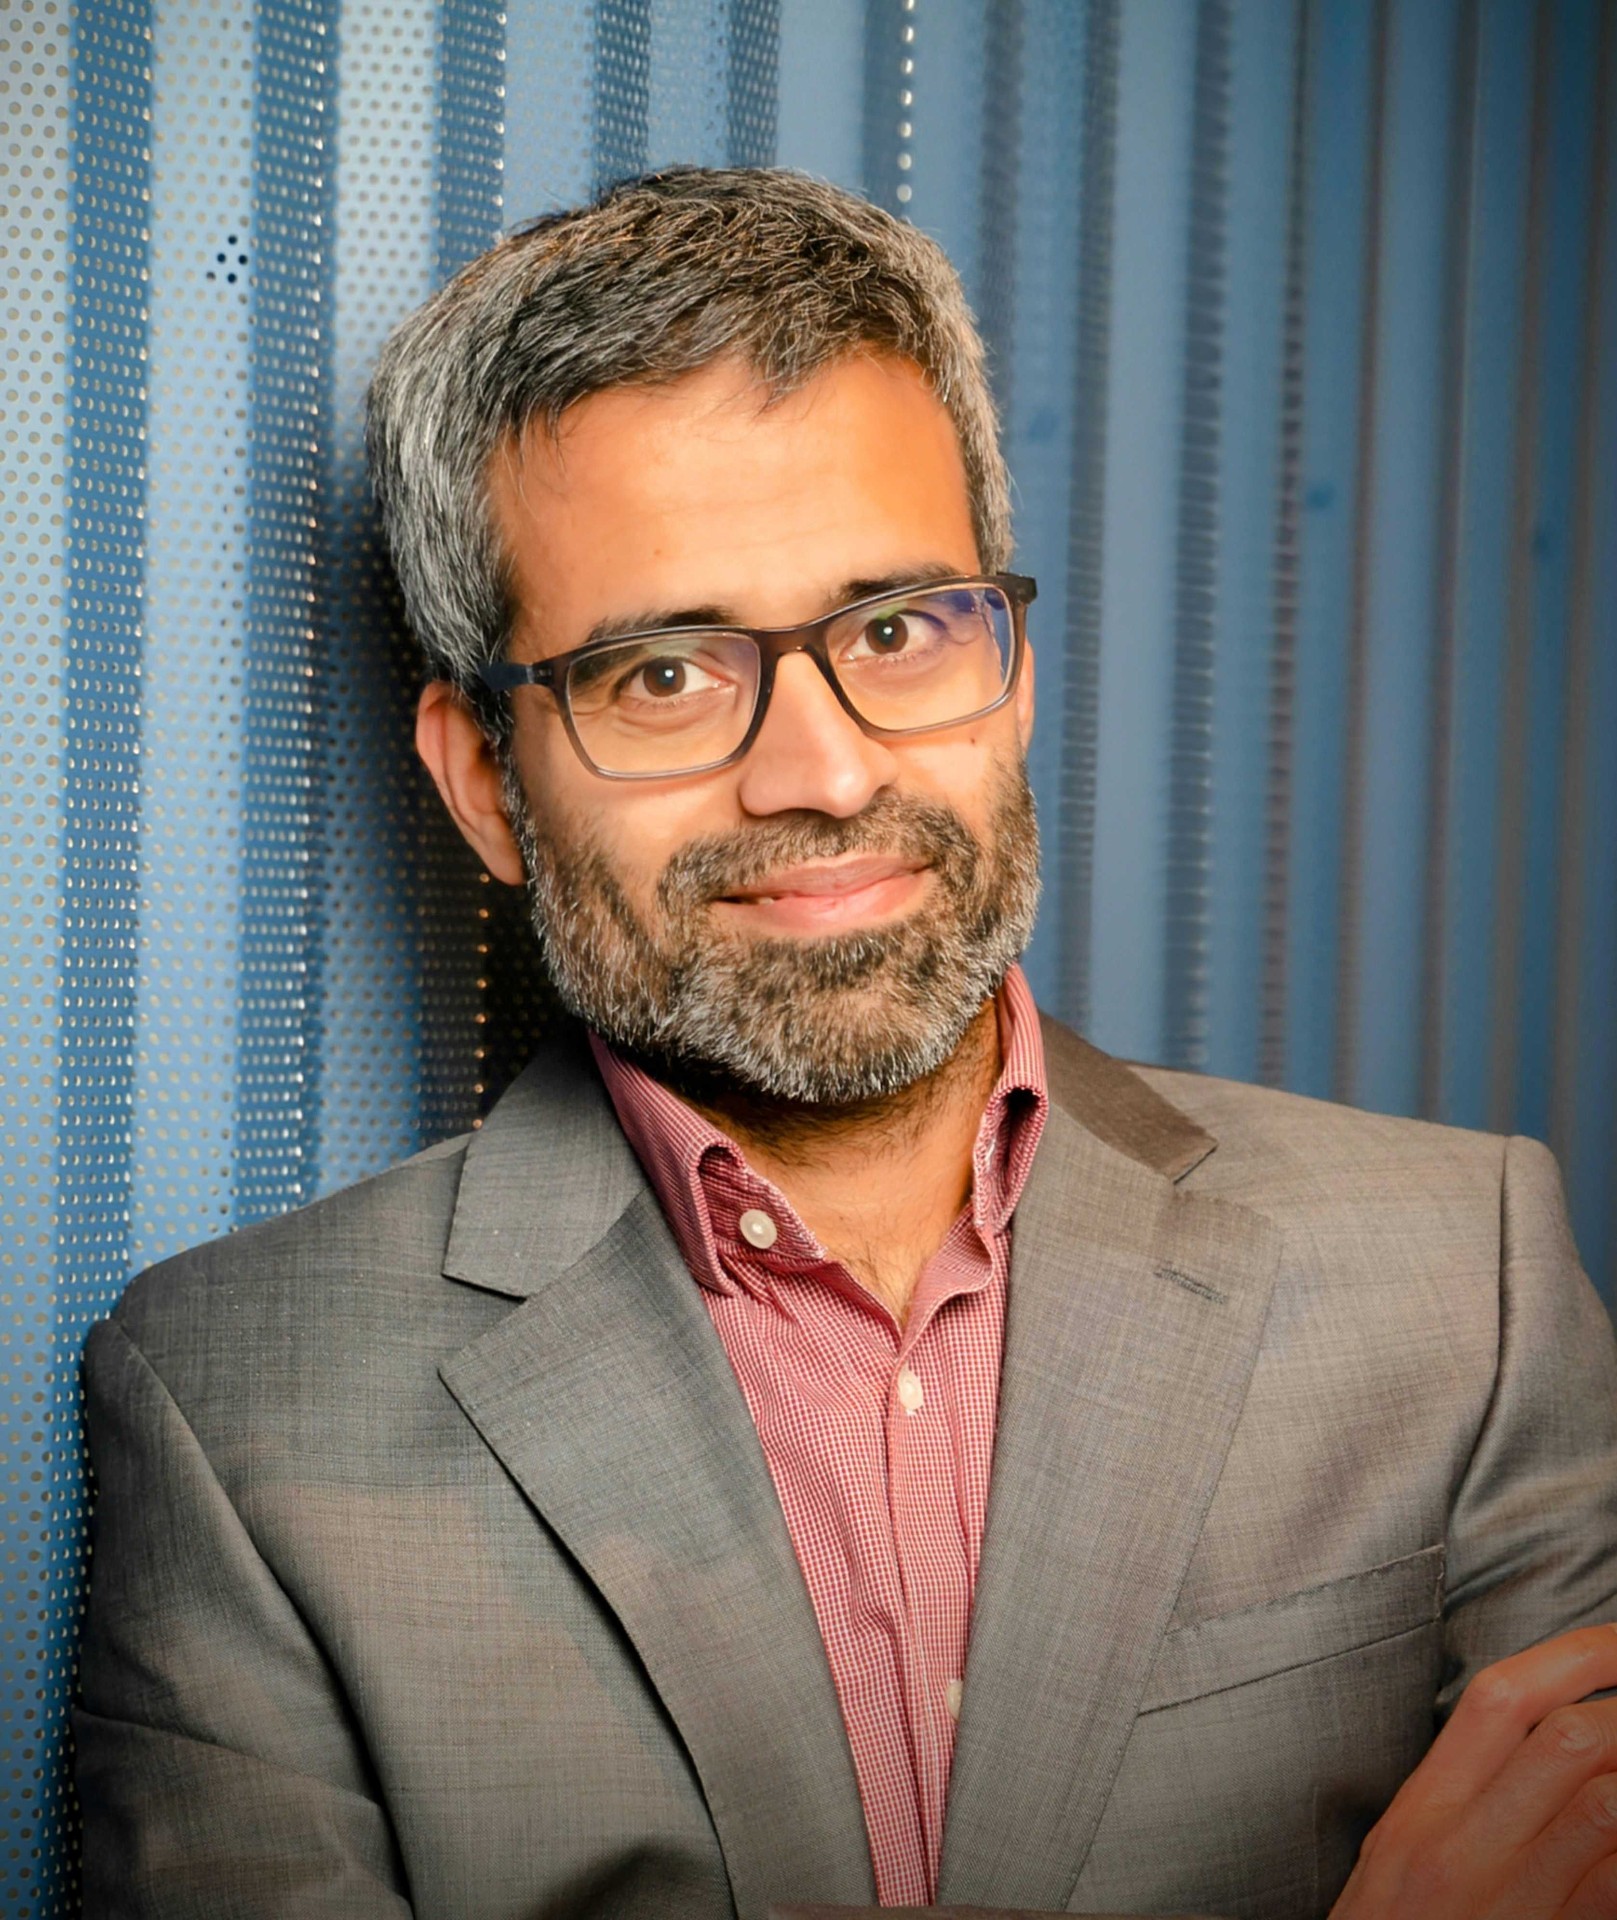
Pradeep Ravikumar
Carnegie Mellon University
-
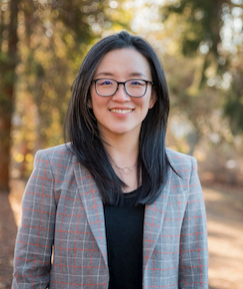
Been Kim
Google DeepMind
-
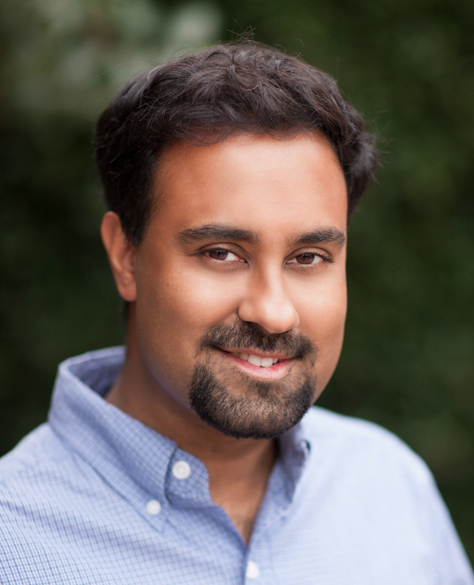
Surya Ganguli
Stanford University
-
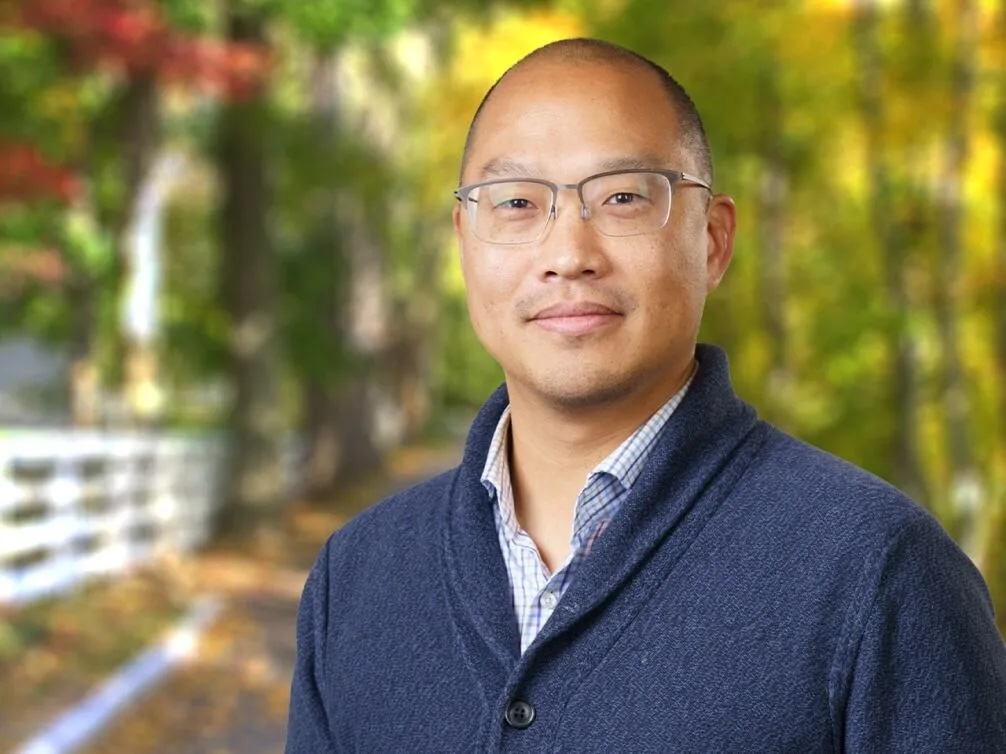
Peter Koo
Cold Spring Harbor Laboratory
-
Francesco Locatello
Institute of Science and Technology Austria
-
Aaron Mueller
Boston University
-
Maxime Peyrard
LIG, Grenoble
-
Chandler Squires
Carnegie Mellon University


